The most useful question to ask conversion rate optimization companies is not how many experiments they can launch. It is how they decide which experiment deserves your traffic, engineering time and attention next. A busy testing calendar can still produce little commercial value if the underlying ideas are weak, the measurements are unreliable or the results cannot inform a decision.
Conversion rate optimization (CRO) improves the proportion of eligible visitors who complete a valuable action. For retailers, that usually means purchases, but the business outcome also depends on margin, returns and acquisition costs. Prioritizing experiments therefore requires more than ranking ideas by their potential conversion lift.
A useful agency process connects customer evidence to commercial value, checks whether an experiment can answer the question and records why one opportunity moves ahead of another.
How conversion rate optimization companies build a decision-ready backlog
An experiment backlog should contain hypotheses, not feature requests. “Add product videos” describes an implementation. “Shoppers cannot judge product scale, so showing a short demonstration will increase purchases without increasing returns” describes a testable explanation.
Each candidate needs a defined audience, observed problem, proposed mechanism and measurable outcome. It also needs an owner who can make the eventual rollout decision. Without those details, prioritization becomes a contest between persuasive presentations.
The outcome must fit the buying journey. For a specialist business offering soundproofing and acoustic solutions, a journey might end in an online purchase or a site-inspection inquiry. A hypothetical experiment for that business model should distinguish purchases from qualified inquiries rather than treat every completed form as equivalent revenue.
That distinction matters when an agency compares experiments across different parts of a site. A high-volume action is not necessarily a high-value action, and a lower-volume inquiry may require downstream sales data before its value becomes clear.
Apply eligibility checks before assigning scores
Before ranking ideas, conversion rate optimization companies should establish whether each candidate belongs in an experiment queue at all. Some items are defects to fix, some require research and others are ready for controlled testing.
A checkout that fails on a supported browser generally calls for remediation and release validation, not an experiment that knowingly preserves a broken experience for half the audience. By contrast, uncertainty about whether delivery information belongs beside the price or beside the purchase button is a reasonable experimental question.
A practical eligibility check asks whether:
| Check | What the agency needs to establish |
|---|---|
| Measurement | The primary event and denominator are reliable |
| Customer evidence | There is a credible reason to expect the proposed change to help |
| Experimental feasibility | Available traffic can support a useful decision |
| Delivery readiness | The team can build, validate and reverse the change safely |
| Business relevance | A positive result would justify an actionable next step |
A failed check does not mean an idea is worthless. It means its next step may be analytics repair, customer research or technical discovery rather than an A/B test.
This separation prevents maintenance work from inflating experiment counts and stops promising ideas from entering tests before they are ready.
Use scoring frameworks to expose assumptions
Frameworks such as ICE, which considers impact, confidence and ease, or RICE, which adds reach, can help structure a discussion. They do not turn uncertain judgments into objective forecasts.
When conversion rate optimization companies present a priority score, ask what evidence sits underneath each input. “High confidence” should mean more than an experienced strategist liking the idea. Relevant evidence could include repeated usability failures, customer service themes, segmented funnel data or results from a comparable experiment on the same site.
Reach also needs a precise definition. A product-page change does not reach every site visitor. A delivery-message test may matter only for shoppers in certain locations or ordering particular products.
Keep the scoring scale simple and explain differences in plain language. One idea might have strong evidence but limited exposure. Another might reach many shoppers but rely on an untested explanation. Those are different investment decisions even if their combined scores happen to match.
Avoid double-counting. If an impact estimate already reflects eligible traffic, multiplying it by a separate reach score can exaggerate its advantage. The purpose of scoring is to make disagreements visible, not to conceal them inside a spreadsheet.
Compare commercial value without pretending to predict lift
The commercial comparison should connect a plausible behavioral change to contribution, not just additional orders. Conversion rate optimization companies can use scenario ranges to compare opportunities while making the uncertainty explicit.
Consider an illustrative experiment with 80,000 eligible sessions per month. Assume a purchase rate rising from 3.0% to 3.3% and $24 in contribution per additional order before experiment delivery costs.
The scenario produces:
80,000 × 0.003 × $24 = $5,760 in additional monthly contribution.
That is a planning scenario, not a forecast or a promised result. A smaller effect would produce less value, and changes in returns, discounts or fulfillment costs could alter the contribution per order.
The comparison should also include implementation costs, ongoing maintenance and how long the improvement could remain relevant. A seasonal experiment with a narrow rollout window may have less realizable value than its annualized estimate suggests.
This is also where commercial evaluation connects with whether CRO services are likely to pay off. Agency fees alone do not determine value. Retail teams need to understand the full cost of generating evidence and acting on it.
Check whether the experiment can answer the question
An attractive business case does not guarantee a measurable result. Conversion rate optimization companies should assess statistical feasibility before committing scarce traffic to a test.
The planning inputs include baseline conversion, eligible audience size, traffic allocation and the smallest effect worth detecting. That last input should reflect the business decision. Designing around a tiny uplift that would never repay implementation costs can make an experiment unnecessarily long.
The experiment specification should define the primary metric, assignment unit, analysis approach and stopping rules before launch. If visitors return across sessions, the assignment method should account for repeat exposure rather than casually switching their experience.
Guardrails protect against narrow wins. A higher purchase rate may be unacceptable if contribution per visitor falls, checkout errors increase or later returns worsen. Some outcomes mature after the experiment itself, so the decision may require follow-up data.
Daily monitoring is useful for detecting errors and harm. Declaring a winner whenever a conventional significance threshold first appears is a different practice and can undermine the analysis. Any sequential stopping approach needs a statistical method designed for it.
When traffic cannot support a useful test, research or a carefully monitored release may be more appropriate. Neither should be presented as equivalent to randomized causal evidence.
Price in delivery risk and dependencies
Engineering effort is more than the time needed to change the interface. It includes instrumentation, accessibility checks, browser coverage, experiment setup, quality assurance and eventual production implementation.
For conversion rate optimization companies, this makes technical discovery part of prioritization rather than an administrative step after the roadmap is approved. A seemingly small change can become expensive if it depends on checkout architecture or introduces performance risk.
Dependencies can also change the order. An analytics repair might deserve immediate attention because it enables several valuable experiments. Conversely, a planned platform migration may make a short-lived customization poor value.
Treat stability and performance problems as readiness issues where appropriate. The same measurement and usability checks used before buying more traffic help establish whether experiment traffic will produce trustworthy evidence.
Every candidate should have a realistic route from positive result to production. If the agency can prototype a winning experience but nobody can maintain it, the apparent opportunity is overstated.
Build a portfolio, not just a ranked list
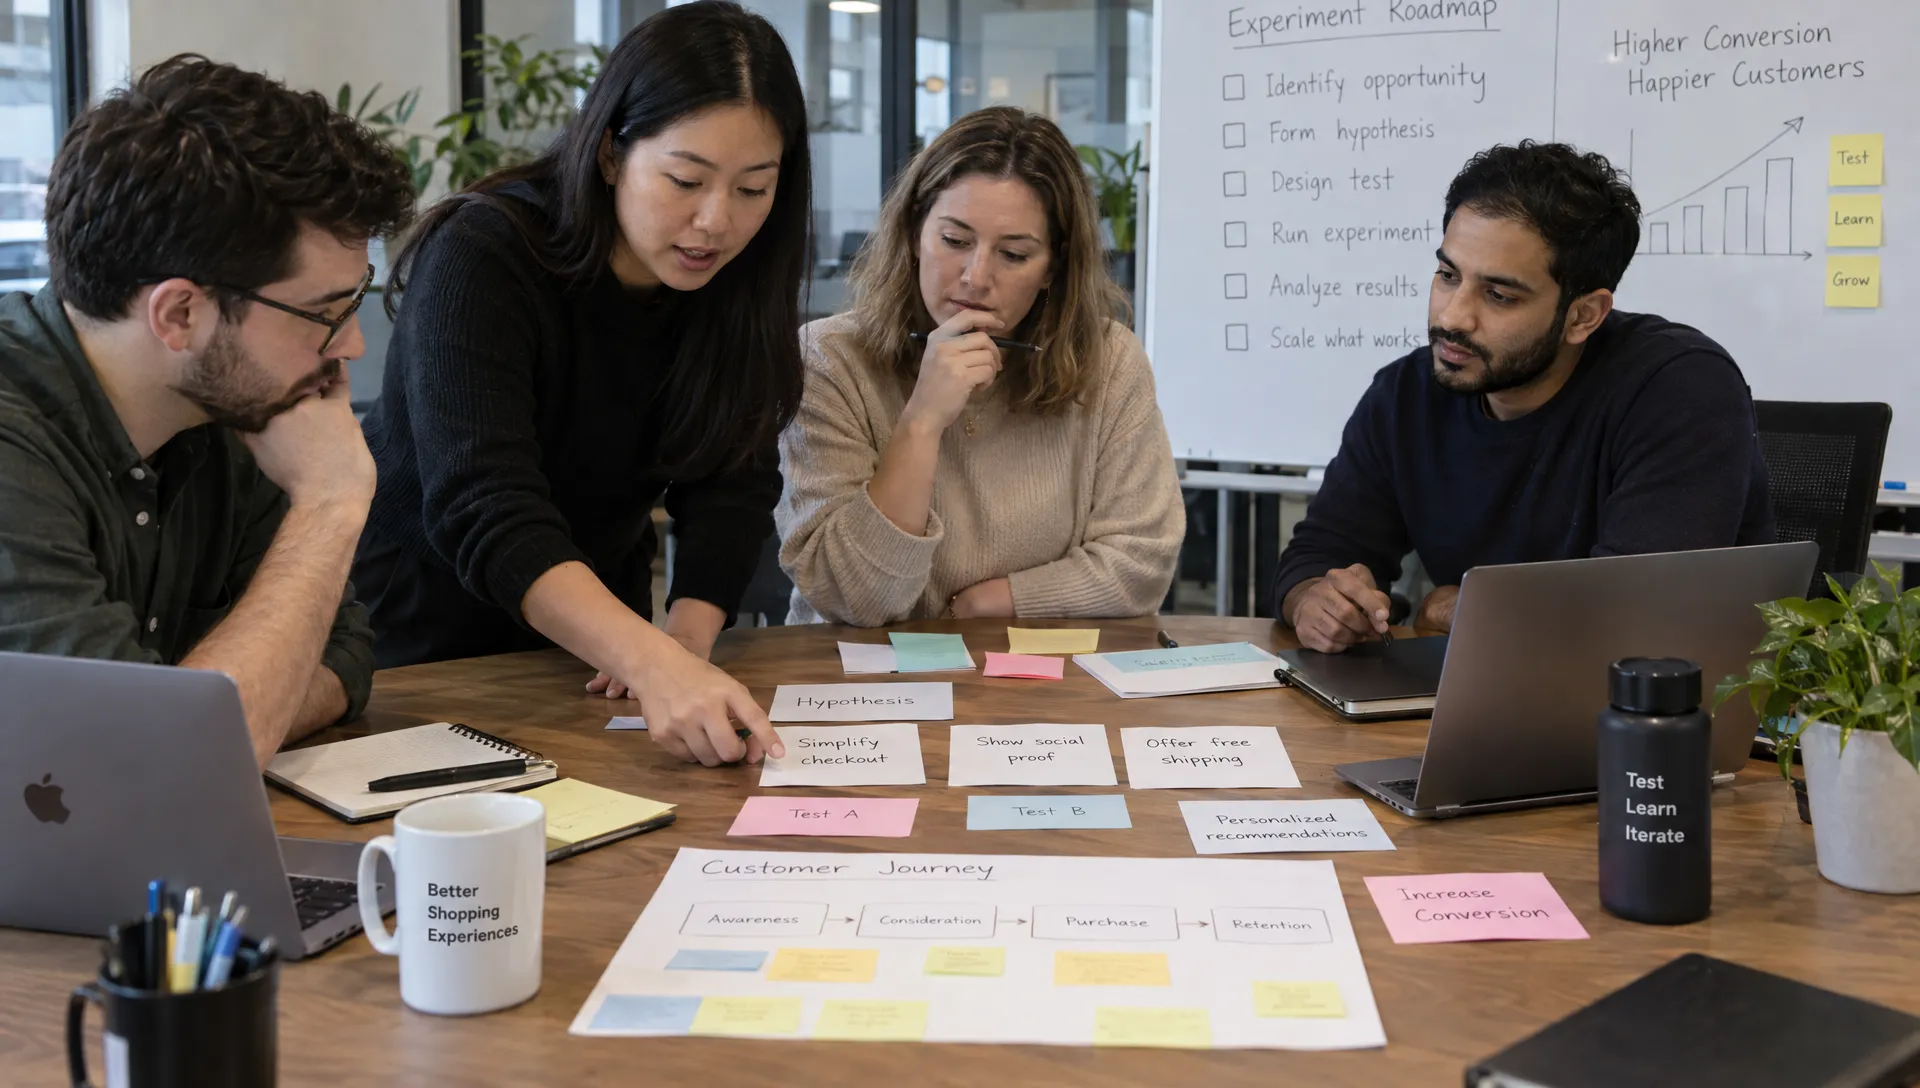
A single ranking cannot capture every scheduling constraint. Conversion rate optimization companies need to balance expected value with available traffic, engineering capacity and the cost of delaying learning.
A hypothetical retail backlog might lead to these decisions:
| Candidate | Main consideration | Appropriate next step |
|---|---|---|
| Broken mobile payment control | Known functional failure | Fix and validate the release |
| Clearer delivery information | Repeated customer uncertainty | Design a controlled experiment |
| Personalized recommendations | Uncertain data readiness | Investigate integration and measurement |
| New navigation structure | Broad reach but unclear customer problem | Conduct targeted usability research |
The table does not claim that delivery information always deserves priority. It shows how different evidence changes the type of work required.
Within the test-ready queue, capacity still matters. Two experiments affecting the same checkout step may interact. Running them together requires a design that can account for that interaction, or a schedule that separates them.
Maintain a mix of near-term commercial opportunities and questions that reduce important uncertainty. A modest test can earn its place if its result will determine whether a much larger investment proceeds. That learning value should be named explicitly, not used as a vague justification for weak ideas.
Reprioritize when results change the evidence
Priorities should change when new information arrives, but not every time a stakeholder suggests another idea. A useful operating rhythm combines a regular backlog review with clear escalation rules for defects, commercial deadlines and material new evidence.
Conversion rate optimization companies should document what each completed experiment changes about the remaining backlog. If clearer delivery information improves purchases, related delivery hypotheses may deserve investigation. It does not prove that every delivery-message variation will work.
An inconclusive result also needs interpretation. It may mean the effect was smaller than the experiment could reliably detect, not that the experiences are identical. A negative result may weaken the underlying hypothesis or reveal an implementation problem. Those explanations should not be interchangeable excuses.
Record the hypothesis, result, uncertainty, implementation cost and resulting decision. Include whether the change shipped and whether longer-term guardrails remained acceptable.
Over time, this decision history becomes more useful than a headline win rate. It shows which assumptions were supported, which were rejected and whether the program improved its ability to choose valuable work.
What to ask an agency before approving its roadmap
The clearest way to evaluate conversion rate optimization companies is to inspect their reasoning on a few actual candidates. A polished dashboard cannot substitute for a defensible decision.
Ask the agency to walk through its top three opportunities and explain:
- What customer evidence supports each hypothesis, and what remains uncertain?
- Why does this outcome matter commercially, beyond increasing an intermediate click or submission?
- What effect can the available traffic realistically detect, and how will the stopping decision work?
- Which implementation, measurement or organizational dependencies could block rollout?
- What would cause the agency to cancel, postpone or deprioritize the experiment?
Also ask who owns analytics validation, engineering delivery and the final business decision. Those responsibilities can sit across several teams, but they should not be undefined.
A credible roadmap leaves room for revision. It explains why the next experiment is the best current use of resources without pretending the entire quarter can be predicted in advance.
Be cautious when an agency promises a fixed number of winners, recommends the same sequence for every retailer or treats conversion rate as the only measure of success.
Frequently asked questions
Do all conversion rate optimization companies use the same prioritization framework? No. Agencies may use ICE, RICE or a custom method. The framework name matters less than the quality of its inputs, the treatment of uncertainty and whether it considers commercial value, feasibility and delivery risk.
What should a low-traffic retailer prioritize? Start with reliable measurement, functional defects and direct evidence from customers. Some improvements may be better handled through research and monitored releases. Switching to a higher-volume click metric can make a test easier to measure, but it does not establish that purchases or profit improved.
Is a 12% conversion rate good? It depends on the action, denominator, traffic source and business model. A purchase rate cannot be compared directly with an inquiry rate or checkout completion rate. Compare consistently defined metrics and check whether stronger conversion also produces stronger economics.
How much should an agency charge for this work? There is no universal fee. Request a scope that separates research, analytics, experiment delivery and ongoing optimization. Clarify whether engineering, implementation of winners and tool costs are included before comparing proposals.
Turn the backlog into an accountable plan
Before approving another test calendar, require a clear hypothesis, commercial rationale, measurement plan and owner for each priority.
Space Dinosaurs combines retail-focused strategy, UX design, analytics and engineering with ongoing optimization. Discuss your current backlog to identify which ideas need more evidence, which technical issues need attention and which experiments are ready to support a business decision.